What happened?
On November 9, 2026, the Strands Agents team published a technical case study explaining how two Amazon engineers replaced Claude Sonnet 4.6 with Strands Decider in a large internal ticketing system.
The system handles different types of internal tickets, including customer escalations, infrastructure capacity requests, automated alerts and security findings. Each ticket needs to be assigned to one of approximately 20 predefined categories.
Previously, the system relied on Claude Sonnet 4.6 to interpret incoming tickets, reason about the available categories and generate structured JSON responses containing the classification.
Although the system worked, the engineers identified an important inefficiency: the application was paying for a powerful generative language model even though the task only required selecting an answer from a fixed list.
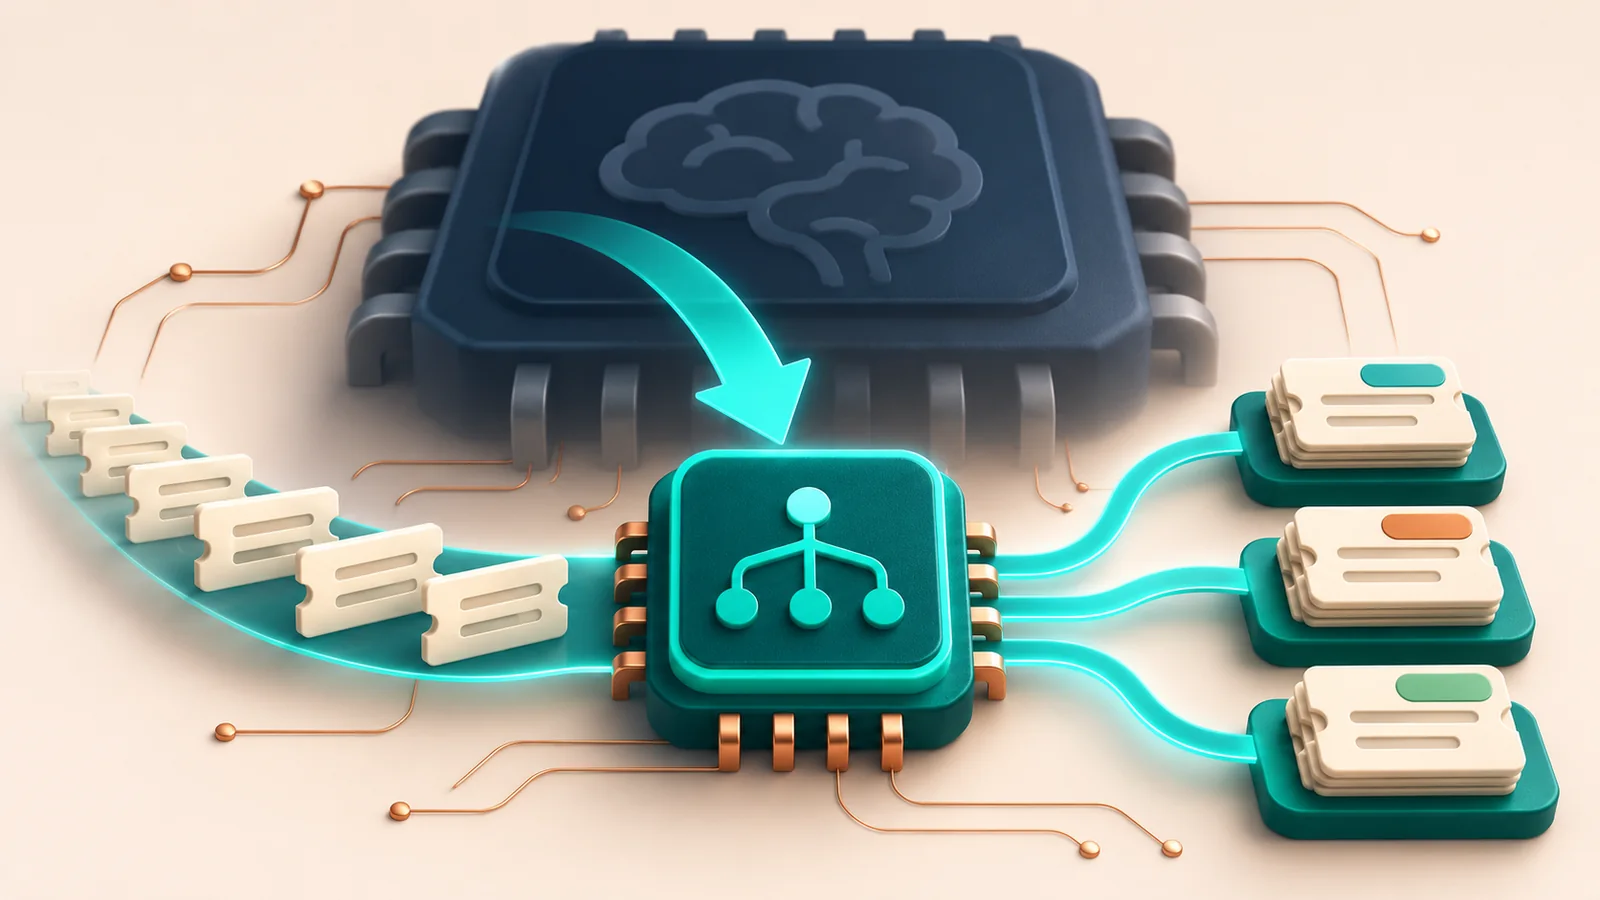
They replaced that workflow with Strands Decider, a specialized decision model designed to select between predefined options and provide confidence scores rather than generate arbitrary text.
The team eventually selected an E4B Gemma 4-based version after evaluating different model configurations.
The engineers reported comparable classification performance and estimated a 98% reduction in model costs. These are figures from the engineering team's own case study, not an independently audited benchmark.
What is Strands Decider?
Strands Decider belongs to a category of AI systems called decision models, sometimes described as System 1 models.
Unlike conventional LLMs, which generate complete text responses, decision models are designed to make specific decisions.
For example, consider a SaaS application receiving this support request:
A customer reports that payments have failed for three consecutive days.
A conventional LLM might analyze the request, explain its reasoning and generate a JSON response containing the appropriate department.
A decision model receives the ticket as input, considers the available choices and returns the most likely category along with a confidence score.
This approach can eliminate unnecessary text generation, reduce token consumption and lower response latency.
The open-source Strands Decider project supports several types of operations:
- Selecting one option from a predefined list.
- Answering yes-or-no questions.
- Scoring or evaluating text against a defined scale.
- Providing confidence scores to help applications decide whether human verification is necessary.
The project is available on GitHub under the Apache 2.0 license.
The performance comparison
The Amazon engineers published the following measurements from their production implementation.
| Metric | Claude Sonnet 4.6 | Strands Decider E4B |
|---|---|---|
| Average call time | 4,215 ms | 897 ms |
| Input tokens per ticket | 6,554 | 2,009 |
| Output tokens per ticket | 170 | 1 |
| Total tokens per ticket | 6,724 | 2,010 |
| Estimated cost per ticket | $0.0222 | $0.0005 |
| Estimated cost per million tickets | $22,200 | $500 |
According to the published comparison, average response time improved by approximately 78%, while total token consumption declined by 70%.
The estimated model cost fell by approximately 98%.
There is an important distinction in these calculations: Strands Decider runs on SageMaker GPU instances, so its costs depend on utilization and available capacity. The approximately $500 estimate includes operational headroom for traffic bursts. The calculation excludes Lambda costs, although the engineers also reported a 74% reduction in average Lambda execution duration.
How Amazon migrated without disrupting production
The engineering team did not immediately replace the existing model.
Instead, it implemented a three-mode configuration using AWS AppConfig.
BEDROCK: The existing Claude Sonnet-based classification system handles incoming tickets.
DUAL: Both models process the same incoming tickets simultaneously. The original model continues handling production decisions while the team compares its output with Strands Decider.
DECIDER: Strands Decider becomes responsible for classification without calling the previous Bedrock model.
This approach allowed engineers to observe real production traffic, compare disagreements and evaluate the alternative before completing the migration.
The team also reported that switching back could be accomplished through a configuration change taking approximately 45 seconds.
One interesting engineering observation was that changing JSON key order could alter the decision model's output probabilities by as much as 0.19. The team standardized key ordering to make its predictions more consistent.
Why this matters for SaaS companies and developers
This case study highlights an important principle for companies building AI-powered software: not every AI operation requires a frontier language model.
Many applications perform repetitive operations such as:
- Customer support ticket classification.
- Email categorization and routing.
- Fraud-risk scoring.
- API request validation.
- Automated workflow selection.
- Customer segmentation.
- Tool selection inside AI agents.
- Content moderation and policy checks.
These operations often involve selecting between predefined choices rather than generating sophisticated explanations.
For SaaS businesses processing thousands or millions of requests, replacing unnecessary generative calls with smaller specialized models could significantly reduce infrastructure costs.
However, decision models are not universal replacements for LLMs. Applications requiring detailed reasoning, explanations, complex instructions or extensive context may still need generative models.
A practical architecture is to use specialized models for routine decisions and reserve larger LLMs for complicated requests or low-confidence results.
What developers should watch next
The growing availability of smaller specialized models could encourage developers to rethink how they architect AI applications.
Instead of routing every operation through a single expensive model, applications may increasingly combine multiple models according to task complexity, latency requirements and operating cost.
The next important development will be whether these approaches demonstrate consistent performance across independently evaluated enterprise workloads.
Why this is trending
Hacker News: The story ranked first in the November 10 daily top-stories snapshot, with 641 points and 223 comments.
GitHub: The open-source Strands Decider repository provides implementation details, model configurations and examples for developers interested in experimenting with specialized decision models.
The discussion is relevant because it challenges the assumption that more capable models are always the best choice for production AI applications.
Editorial verification note: The rankings, points and comment counts above are reproduced from the supplied briefing. The currently accessible Hacker News daily snapshot does not substantiate those exact statistics; they remain unverified.
Sources and further reading
- Strands Agents — November 9, 2026. Amazon saves millions by replacing Sonnet 4.6 with Strands Decider. Original engineering case study and performance comparison.
- GitHub — Strands Decider repository. Open-source implementation and model documentation.
- Hacker News — November 10, 2026. Daily top-stories snapshot and community discussion.
Further reading
Building a product in this space?
MORE FROM THE NEWSROOM
Related news
 Artificial Intelligence
US Moves to Regulate Remote Access to Advanced AI Chips Through Overseas Data Centers
The US Department of Commerce has released an interim final rule targeting remote access to advanced American semiconductors through overseas data centers. The measure introduces licensing requirements for certain high-volume computing arrangements serving companies headquartered in restricted destinations and adds destination-based controls for advanced chip exports to five countries.
 Artificial Intelligence
OpenAI Launches ChatGPT Wallet, Letting AI Agents Complete Purchases With User Approval
OpenAI has introduced ChatGPT Wallet, a payment feature that allows its AI agents, called Dots, to complete online purchases after users review and approve each transaction. Developed with American Express, Mastercard and Visa, the initial rollout is limited to eligible US ChatGPT Pro subscribers.
 Artificial Intelligence
Cerebras Raises 2026 Revenue Outlook After 55% Quarterly Growth, but GAAP Losses Widen
AI hardware company Cerebras reported record third-quarter revenue of $210.8 million and raised its full-year 2026 revenue outlook. Its cloud and inference business grew rapidly, but the results also revealed a much larger GAAP net loss, highlighting the financial challenges of scaling advanced AI infrastructure.